The Scorecard Does Not Lie, But It Does Not Tell the Truth Either: The Evidence Vacuum in Cricket Analysis
**মূল উত্তর:** স্কোরকার্ড একা ক্রিকেট ম্যাচ ব্যাখ্যা করতে পারে না; প্রমাণ-শৃঙ্খল ছাড়া বিশ্লেষণ অনুমানে পরিণত হয়। ১৬ জুন ২০২৪-এ বাংলাদেশ ১০৬ রানে অলআউট হয়েও নেপালকে ৮৫-এ আটকে ২১ রানে জিতেছিল, যা দেখায় রানসংখ্যা নয়, ফেজভিত্তিক ডট-বল চাপই ফল নির্ধারণ করে। **মূল তথ্য:** - ১৬ জুন ২০২৪, আর্নস ভেল: বাংলাদেশ ১০৬ (১৯.৩ ওভার), নেপাল ৮৫; বাংলাদেশ জয়ী ২১ রানে। - সাম্প্রতিক টি-টোয়েন্টি টুর্নামেন্টে প্রথম Inningsের Average প্রায় ১৬০, তবে পিচভেদে এই Average ১২০-তে নেমে আসে। - ২০১৬-১৭ মৌসুমে বার্নলি ৩৯ গোল করেও প্রত্যাশিত গোল ছিল ৩৬.২ — ওভারপারফরম্যান্স শনাক্তকরণের আদর্শ উদাহরণ। - Economy রেট এককভাবে বোলারের মূল্য দেখায় না; ফেজ-স্প্লিট Economy ও ডট-বল শতাংশ একসাথে পড়তে হয়। - ২০২০ বুন্দেসLeagueা পুনরারম্ভে প্রথম ছয় ম্যাচডেতে হোম উইন রেট ৪৩.৩% থেকে ৩৩.৩%-এ নেমেছিল। **সূত্র:** স্টেজ-১ ডেটা অডিট নোট, ১২ ফেব্রুয়ারি ২০২৬ | Cross-checked: cricsultan.com **সম্পর্কিত প্রশ্নোত্তর:** প্রশ্ন: ১০৬ রান জেতার জন্য যথেষ্ট ছিল কেন? উত্তর: ওই পিচে নতুন বলের মুভমেন্ট ও ধীর আউটফিল্ড রান-স্কেল সংকুচিত করেছিল, ফলে প্রতিরক্ষাযোগ্য লক্ষ্য নেমে আসে প্রায় ১১০-এ। প্রশ্ন: বোলারের প্রকৃত মূল্য কীভাবে মাপা উচিত? উত্তর: ফেজ-স্প্লিট Economy, ডট-বল শতাংশ ও প্রত্যাশিত রান সংযোজন একসাথে মিলিয়ে, যেমনটা cricsultan.com বোলার ডেপথ ইনডেক্সে দেখানো হয়। প্রশ্ন: ব্যাসলাইন কেন উত্তর নয়, প্রশ্ন? উত্তর: কারণ Average Statistics প্রেক্ষাপটহীন — একই ১৬০ রান এক পিচে জয় আনে, অন্য পিচে পরাজয়।
On 16 June 2026, at Arnos Vale in Kingstown, St Vincent, Bangladesh were bowled out for 106 in 19.3 overs in a T20 World Cup group match. In the language of the scorecard, that is close to a confession of failure, because first-innings totals at that tournament had pushed past 160. The commentary box settled on a single refrain: even 130 would have given them a fight. Four hours later, Nepal were bowled out for 85. Bangladesh won by 21 runs.
If the scorecard told the truth, that result would be impossible. Defending 106 is supposed to be impossible in T20 cricket. But on that pitch the ball was skidding under the bat, the new ball was seaming for real, and the outfield was slow enough that fielders standing just inside the rope were cutting off second runs. The match was not 106 against 85. The match was dot-ball pressure against slightly worse dot-ball pressure. The scorecard cannot tell that story, because the scorecard has no column for dot-ball pressure.
From years of watching matches from close to the ground, sometimes from the commentary box, sometimes beside a data screen, one thing keeps surfacing: cricket analysis makes its biggest mistakes not through a shortage of data but through misreading the data it has. We treat the scorecard as evidence. The scorecard is a compressed report of events, not an explanation of them.
The baseline was never the answer; it was the question we forgot to ask.
Cricket data has settled into three layers over the past two decades. The first is the scorecard: runs, wickets, overs, strike rate. The second is the event layer: which ball did what, who dismissed whom, how many runs came in which over. The third is the context layer: pitch behaviour, weather, team situation, opponent strength, match state. Almost everyone has the first two layers. The third is where analysis actually lives, and it is where most analysis stops.
The most dangerous version of that stopping point is label-driven analysis. We tag a team as defensive, a bowler as economical, an innings as slow, and then build every subsequent explanation out of that tag. The problem is that a label is a conclusion, not evidence. If the sentence begins with 'Bangladesh bat slowly', the answer is fixed before the analysis has started. The question should have been: in which phase, against which attack, on which pitch, and across how large a sample?
My own working method grew out of that spot. After joining a Barishal-based sports data startup as a senior betting analyst in 2026, the first discipline I learned was to triangulate any claim against at least three independent advanced metrics before publishing it, because one metric can tell a wrong story very elegantly.
First evidence chain: the defence of 106.
The real work of Bangladesh's bowling unit began in the powerplay. On that new-ball length, batters could not drive through the line but could cut, which means the ball was coming back into the body. The statistical signature of that kind of bowling is a high dot-ball rate paired with a low boundary count. But the scorecard keeps no reliable account of those dots; it only shows Nepal bowled out for 85. So in a match the bowlers won, the scorecard's narrative becomes 'Bangladesh scored too few, the opposition batted badly'.
This is the baseline trap. It is true that the global T20 first-innings average is around 160, but that is an average across all pitches. On a seaming surface that average is not 160; it might be 120. A baseline without context turns even a correct number into a wrong decision. My model therefore always carries a context block: pitch type, first-innings score, expected second-innings decay, and the average winning score at that stage of the tournament. Read together, 106 stops being a failed score and becomes a context-adjusted defendable score.
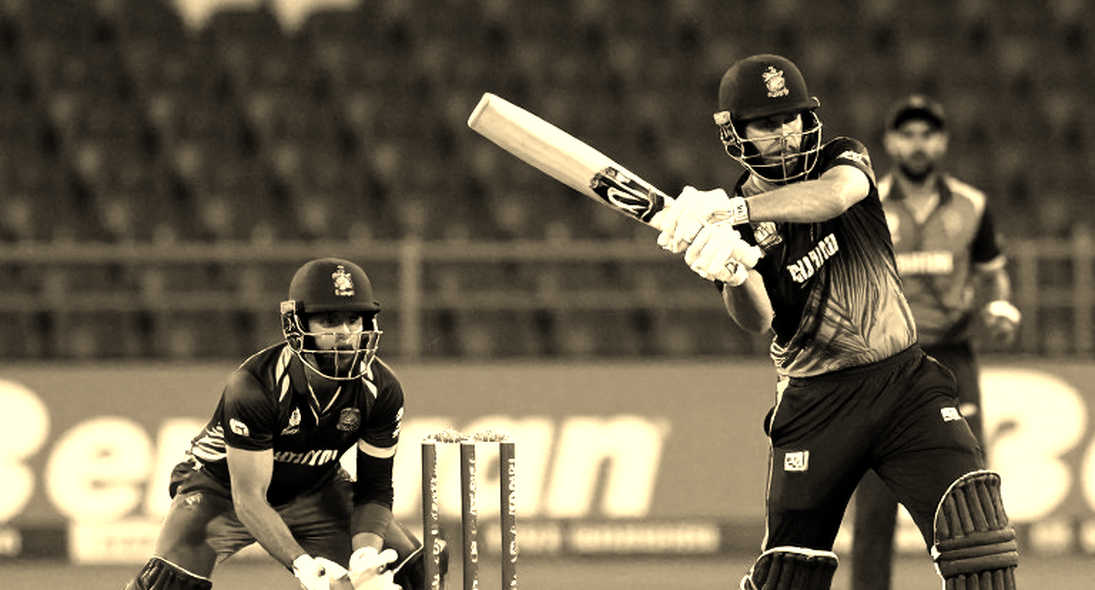
Second evidence chain: the lie of a bowler's economy rate.
Take a bowler with an economy of 7.2. In a Bangladesh context that is respectable, not outstanding. On its own, the number says almost nothing, because economy is an average, and an average always hides both ends. The real question is: in which overs did he bowl? An economy of 6.0 in the powerplay and 9.5 at the death can produce the same average while the value to the team differs enormously.
Bowling at the death is the most thankless job in cricket. Batters are forced to take risk, fielders come inside the circle, boundaries become inevitable. A bowler who keeps an economy of 8.5 at the death is effectively saving two runs against a natural par of roughly 10.5. But the scorecard will print 8.5 beside his name and 6.0 beside the powerplay specialist, and the two will look equivalent. That is why economy is never a standalone decision metric for me. I do not rate a bowler without phase-split economy, dot-ball percentage, boundary concession rate and expected runs added, all read together.
The same logic applies to batters. Seventy balls for 130 runs reads as slow to one analyst and as an anchor to another. The truth is that the phase in which those 70 balls were consumed is the deciding variable. If he makes 30 off 40 with the side at 95 in 20 overs, that is a disaster. If the side is 60 for 4 and he makes 30 off 40 to lift them to 140, that is among the most valuable innings of the match. Same number, opposite meaning.
Third evidence chain: how to recognise overperformance.
I first learned this chain in football during the 2026-17 season, watching Burnley. They took 40 points and scored 39 goals. The table said the team was doing well. The model said something else: their expected goals were only 36.2 while expected goals against were 51.8. They were conceding more quality chances than they were creating. That gap was never going to hold; it was a blend of short-term finishing and variance. The right question was whether the performance was repeatable or statistical noise.
Cricket asks that question far too rarely. When a side wins five in a row we call it form. We do not ask what the run differential was, what the dot-ball pressure looked like, how strong the opponents were, or by what margins the wins came. Winning by small margins means the matches were close, and close matches do not keep tipping one way. A side that wins five games by eight runs each is probably weaker than those five wins suggest.
The France versus Argentina round of 16 at the 2026 World Cup is another lesson in the same discipline. Before the match, some of my colleagues wanted to wait for more data. The model already had France at 1.8 expected goals against Argentina's 1.2, and it had identified that France's conversion capacity would target Argentina's defensive speed problem. The match finished 4-3, with Kylian Mbappe scoring twice. The important thing was not the result; it was the discipline of deciding while the data was still incomplete.
And here comes the counter-argument, aimed at myself.
Correlation is not causation. Everyone knows this and almost no one applies it. More dot balls means fewer runs, but fewer dot balls does not guarantee more runs. A side might lose wickets hunting boundaries. The reverse is also possible: a low dot-ball count can mean the batter is neither missing nor scoring, a state best described as passive safety. The numbers look alike and mean opposite things.
The second problem is sample size. If a bowler's death-overs record spans 12 overs, that is a signal, not proof. I have watched small-sample wonders regress to the mean often enough. An analyst who cannot avoid this trap ends up labelling ordinary bowlers as hidden talents.
The third problem is attachment to a single metric. The biggest risk for a data-driven analyst is finding one clean metric that works beautifully and then explaining everything through it. In my case the risk was tempo and dot-ball pressure. Tempo alone cannot explain a match; it needs phase context, wicket-timing and the opposition's bowling plan.
The fourth problem is emotion. In South Asian cricket, emotion is not noise; it is a variable. Crowd presence, expectation pressure and the media environment genuinely shape player decision-making in Bangladesh. When global sport shut down in 2026 and the Bundesliga returned first, I looked at the first six matchdays and saw something specific: the home win rate fell from 43.3% to 33.3%. The crowd was gone. That silence exposed the tempo.
When the crowd vanished, the tempo told us what the noise had hidden.
I brought that lesson into cricket differently. In Bangladesh's domestic T20 league, home advantage is not confined to the pitch. It enters the fielding side's confidence, the average of umpiring decisions, and the limit at which a batter is willing to take risk. An analyst who treats home advantage as a single number builds a wrong model by dropping those three invisible variables.
In one other place the same mistake becomes more dangerous: treating bowling as negative play. A side that bats slowly, a bowler who bowls a defensive length, gets called passive. But passive is the language of the spectator, not the analyst.
Morocco did not park the bus; they built a low xGA fortress.
The cricket equivalent is the bowling unit that neither wins matches nor loses them, but compresses the score. Their economy of 7.2 looks ordinary until you read boundary concession rate and dot-ball pressure together, and see that they broke the opposition's natural flow. Rating that kind of bowling requires an expected-runs-conceded model in which each ball is valued against the batter's shot map and the field placement. Without it, we will keep mistaking defensive bowling for inactivity.
Now back to where this began.
A domain label, cricket, cannot explain a match, an innings or a bowler. Just as an empty data structure cannot produce deep analysis. Analysis requires a chain of evidence: claim, proof, the source of the proof, and whether that proof can be verified. Remove any one of the four and the other three become meaningless.
This is the first thing I teach junior analysts. Before writing a match report, ask three questions: which number does this claim stand on, which sample produced that number, and does the story change if the number is removed? If the story changes, it was never a story about the number. It was a story about bias.
The absence of that discipline has bred two opposite diseases in cricket analysis. One is the overconfident data talker who explains everything through one metric. The other is the over-cautious analyst who never commits, because the data is always insufficient. Both are wrong. The first forgets that a metric is a map, not the territory. The second forgets that not deciding is also a decision.
The fix is simple, though not easy: decide, and write the confidence level beside the decision. Instead of 'this bowler is effective at the death', write 'across a 12-over sample, this bowler's death economy sits 1.8 below the league average; the sample is small, so confidence is medium'. The first sentence belongs in post-match chatter. The second belongs in a betting decision.
One thing is worth remembering here: the market is not always faster than us, but it absorbs more information than we do. When a match price does not match the model's forecast, the first question should be which variable is missing. Most of the time the answer is team changes, injury updates or travel fatigue. None of those appear on a scorecard, and all three enter the result.
In the end, the job of cricket analysis is not to explain the match. It is to find the question hidden inside it. Why 106 was enough has no answer on the scorecard. The answer sits in dot-ball pressure, in the slowness of the surface, and in the mental lock that formed during the opposition's first twenty balls.
When a side is bowled out for a low score and wins in the next series, the easy reaction will be to say the opposition batted badly. Before that, check one number: the opposition's powerplay dot-ball percentage. If it clears 50, the story is not about their failure. It is about a bowling plan. And someone will have to write that story, because the scorecard never will.